Pradeep Kaushik·Jul 11, 2026·Untangle·7 min read·Updated Sep 21, 2026
In this article 5 sections
I used one training pipeline for two tasks: a cart balancing a pole through trial and error, and a Franka arm stacking cubes from demonstrations. The build note records the runs. Here I want to explain why those methods put the work in different parts of the same five-stage loop, and how I would choose the next learning setup.
The two methods I ran
I ran two common learning methods, one for each task.
Reinforcement learning (RL) learns by trial and error against a reward. The policy acts, the environment returns a scalar reward, and an algorithm (PPO, in my Cartpole run, via rsl_rl) updates the policy toward higher-reward behavior. My PPO setup used no demonstrations, so the policy had to interact with the simulator during training to find out what worked. Other RL setups can use demonstrations or offline data; this one did not.
Imitation learning (IL), specifically behavior cloning (BC), learns by copying. The policy is given demonstrations — recorded (observation, action) pairs — and trained with ordinary supervised learning to reproduce the action given the observation (robomimic’s bc_rnn_low_dim, in my Franka run). The correct actions are already in the dataset, so training is offline pattern-fitting over a fixed file, with no environment interaction while it learns.
In my setup, RL avoided demonstrations but needed a reward, and the reward was the awkward part. A reward for “keep the pole up” is a one-liner. A reward for “stack these cubes” can become brittle: I would have to specify what counts as a good grasp, lift, and placement, and each term creates another way to score without completing the task. For this contact-rich, multi-step example, demonstrating success was easier than scoring every part of it, so I used imitation and shifted the simulator from training arena to data factory. That is a task choice, not a claim that manipulation always belongs to imitation learning.
In these runs, PPO needed the simulator during training, while behavior cloning learned from a fixed file. That distinction explains the different handoffs below; it is not a claim that all reinforcement learning must use live simulation.
Scroll sideways for more columns.
Stage
Reinforcement learning (Cartpole)
Imitation / BC (Franka)
Is the sim running?
Capture
Skipped — a reward function, no demonstrations
10 seed human demos (HDF5)
RL: n/a · IL: no (downloaded)
Simulate & Synthesize
Env config only; instantiated at Train
Mimic expands 10 → 1,000 demos (~46 min)
IL: heavily
Train
PPO inside the sim (4,096 environments)
Supervised BC, offline on the dataset
RL: yes · IL: no
Validate
Roll the policy out in sim
Roll the policy out in sim
both: yes
Deploy
ONNX export + latency benchmark
Inference only
both: no
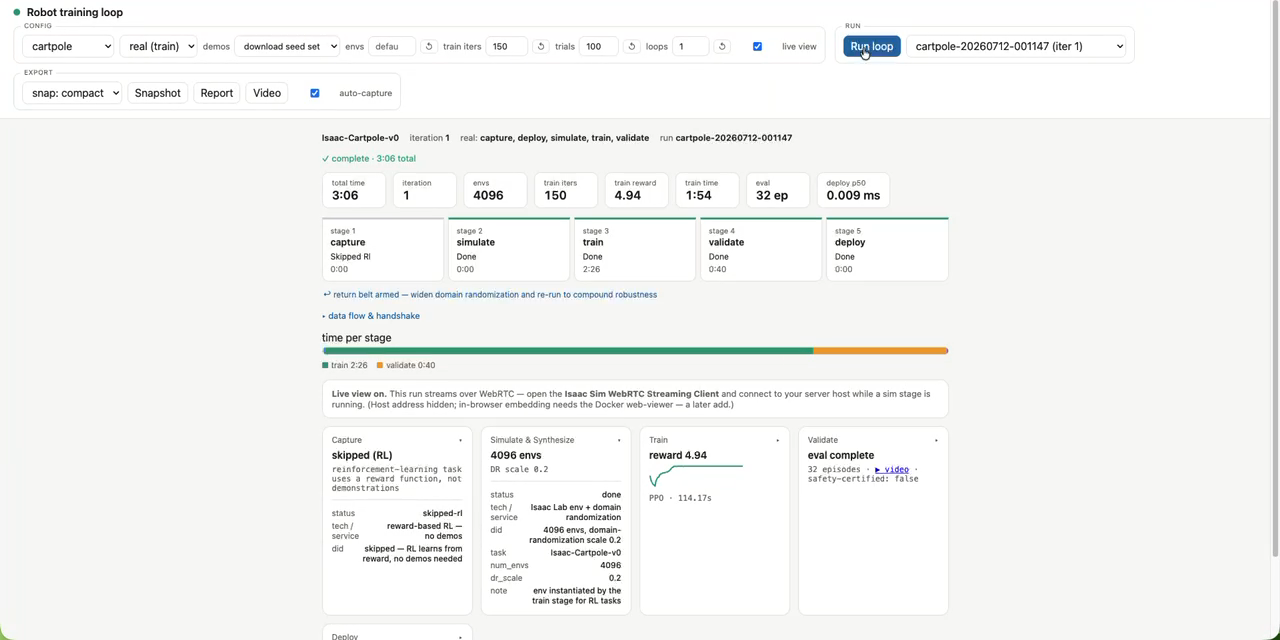
The reinforcement-learning shape in the actual interface. Cartpole skips Capture, treats Simulate as configuration, and spends nearly all of its three minutes in Train. The completed view also keeps the evidence attached to the stages: reward curve, evaluation count, policy video, and deployment latency.
Where the sim’s role flips
The simulator changed jobs. In Cartpole it generated the learning experience during Train. In the Franka path, Mimic generated demonstrations before training, and simulation returned afterward to evaluate the fitted policy. That moved the longest stage from Cartpole training to Franka data generation.
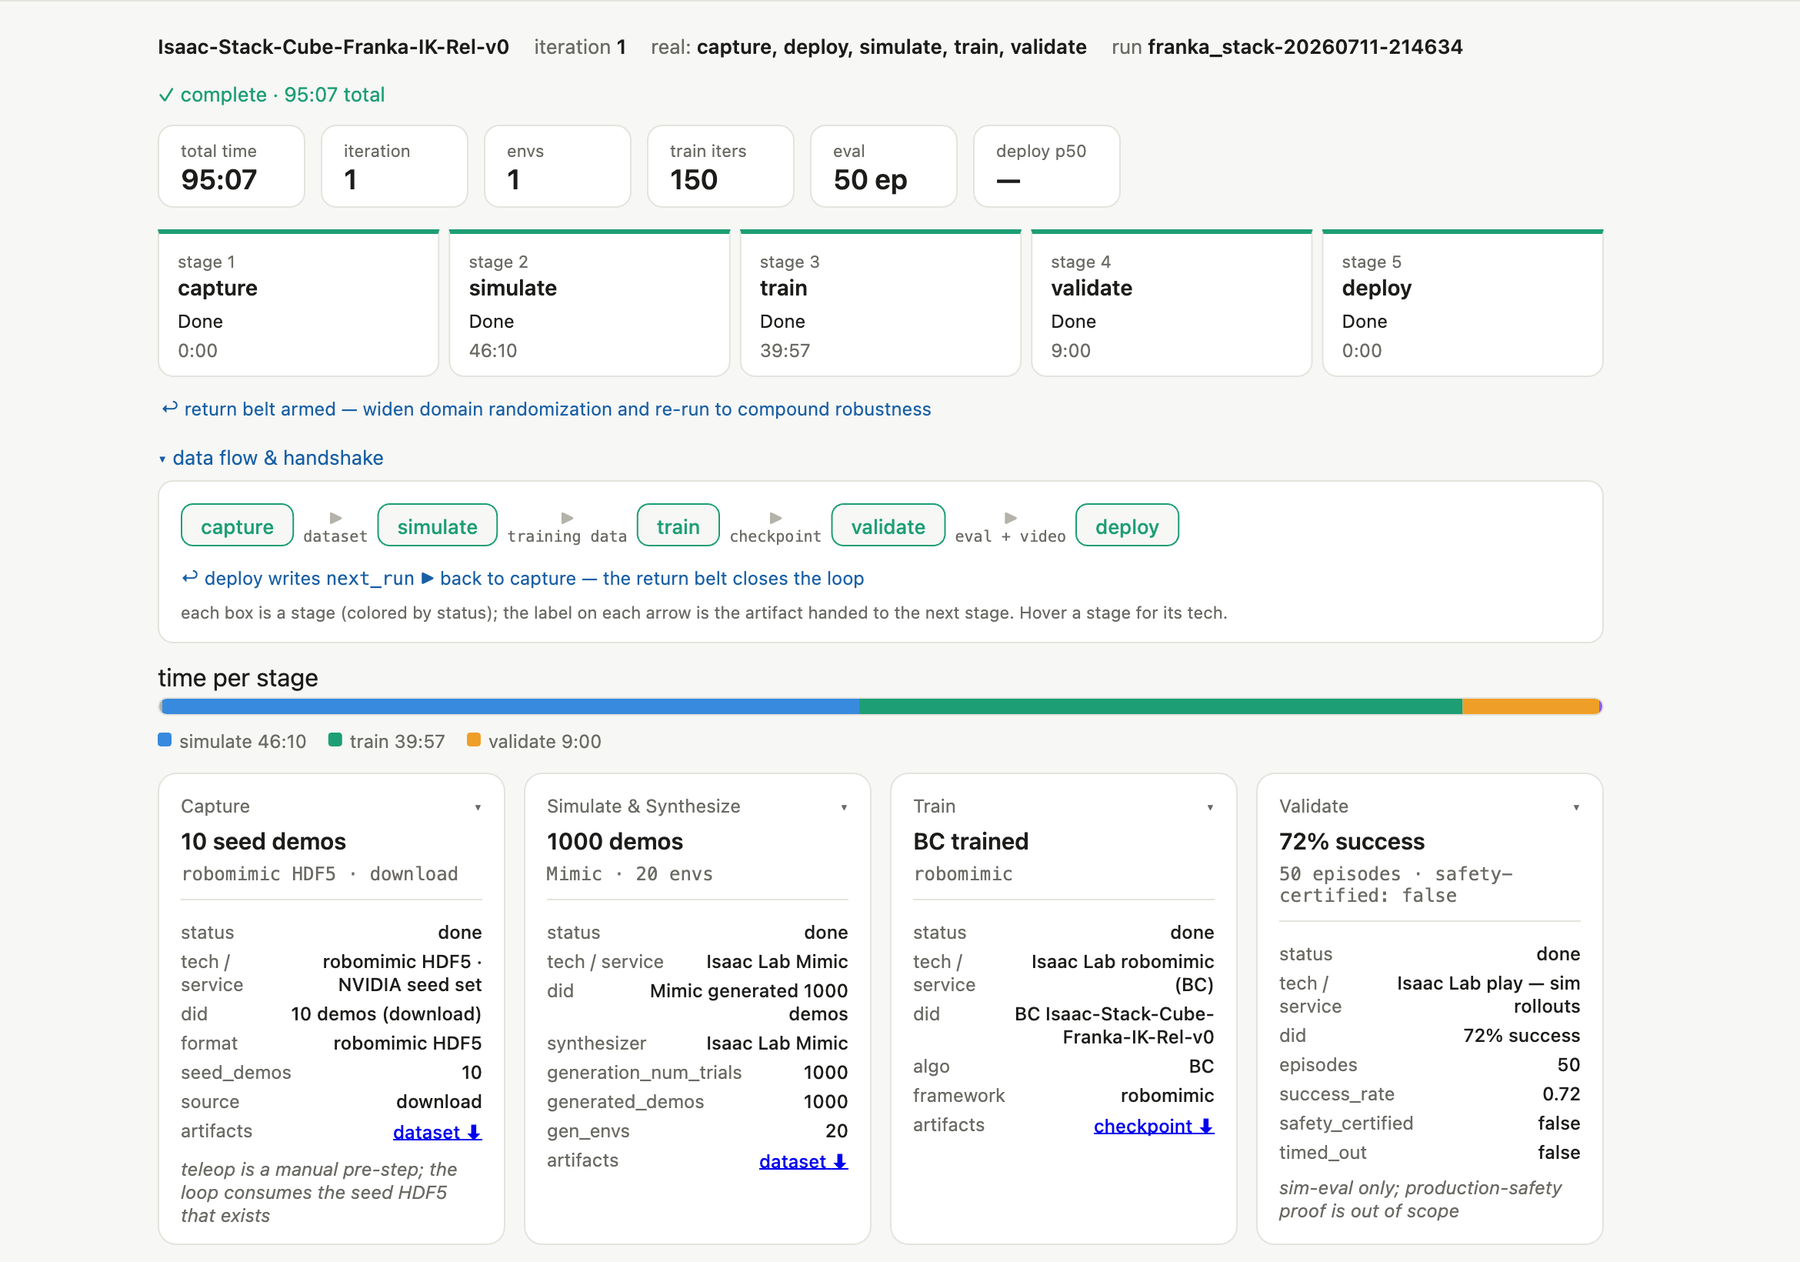
The imitation-learning shape, with the handoffs exposed. Capture starts with ten demonstrations; Mimic expands them to 1,000; Train fits behavior cloning offline; Validate returns to simulation and reaches 72% over 50 episodes. The expanded cards are useful here because they show what crossed each stage boundary, not just that the stage completed.The same five stages, two shapes. Teal marks where the simulator is actually running; the amber outline marks each method's slow stage. In these two runs, Cartpole uses simulation during Train, its slow stage. Franka uses it to generate data before offline training. Both return to simulation for validation; deployment differs, with ONNX export and latency for Cartpole and inference-only execution for Franka.
Why I used imitation for this manipulation task
Choosing imitation moved the next question to data coverage: how much variation could I get from the demonstrations I had? Mimic expanded the small seed set across randomized conditions. The ten seed trajectories were human demonstrations supplied with the task; Mimic generated simulated variations of them. On my box, the run with 50 generated demos reached about 2%, while the run with 1,000 reached 72%, from the same ten seeds. Because I changed the dataset size across two runs without controlled repeats, I treat that as a strong clue about data variety, not a measured law.
Which method needs which parts of the loop
Different jobs put the weight on different stages:
Scroll sideways for more columns.
The job
Method
Where the work lands
Balancing, locomotion, walking, flight
Reinforcement learning
Train — a reward is cheap to write, exploration is safe and fast in sim
Stacking, insertion, pouring, folding
Imitation
Capture + synthesis — the task is easy to show, hard to score
Assembly, long-horizon, sparse-reward
Hybrid (BC warm-start + RL fine-tune)
Both — demos bootstrap exploration, reward polishes the last mile
A useful starting question is whether the task is easier to score or to show. A clean reward made RL a good fit for Cartpole; demonstrations made imitation a simpler first fit for the cube stack. Hybrid, offline-RL, and demonstration-assisted methods blur that line, so it is a starting point rather than a taxonomy.
This is also where the article’s “own the middle, rent the edges” claim became concrete, with one correction. The same pipeline and report contract carried both tasks even though Simulate and Train did different work. That reuse is real in this build. Whether the middle is the durable thing worth owning — technically or commercially — is still open, because the seed data coming through Capture may matter more than the plumbing around it.
What I haven’t tested yet
Building the loop established the mechanics. It also left a handful of things where I have an opinion but haven’t done the run to back it up — so I’ll mark each one as untested by me, not settled.
Transfer and safety on hardware. The Franka result was 72% success over 50 simulated episodes. Every run reports on_robot: false and safety_certified: false. I have not tested a physical Franka or established a safety case; a higher simulation score would not supply either one.
Whether owning the middle is the right bet. The generated dataset changed from 50 to 1,000 demonstrations while the ten seeds stayed the same. Those runs do not isolate seed quality or establish that it was the biggest lever. I still think the captured data may be more valuable than the reusable pipeline, but that is an ownership hypothesis, not a result of this comparison.
Whether the flywheel actually compounds. The return belt works mechanically — Deploy writes next_run, the next run reads it. What I haven’t done is run it a few times in a row and watch the success rate climb as fresh data flows back. To show it, I’d deploy, collect the rollouts, add them to the dataset, retrain, and repeat. I think it compounds; I just haven’t watched it happen.
Whether a stronger method beats plain behavior cloning. This behavior-cloning run plateaued near 70%. I did not isolate whether that came from the method, the data coverage, the training setup, or run variance. A useful next comparison would warm-start from the demonstrations and fine-tune with reinforcement learning, or post-train a larger model on the same data. I expect one of those to improve the result, but I have not run it.
These runs used the NVIDIA stack I know best, without a comparison against the alternatives. For the next task I would start with the learning signal: a reward I can specify and test, demonstrations I can trust, or a combination. I would then check the corresponding data and simulation path before expanding the training platform.
Disclaimer: The views and opinions expressed in this account are those of my own and do not represent those of my employer, NVIDIA.